What is bot detection?
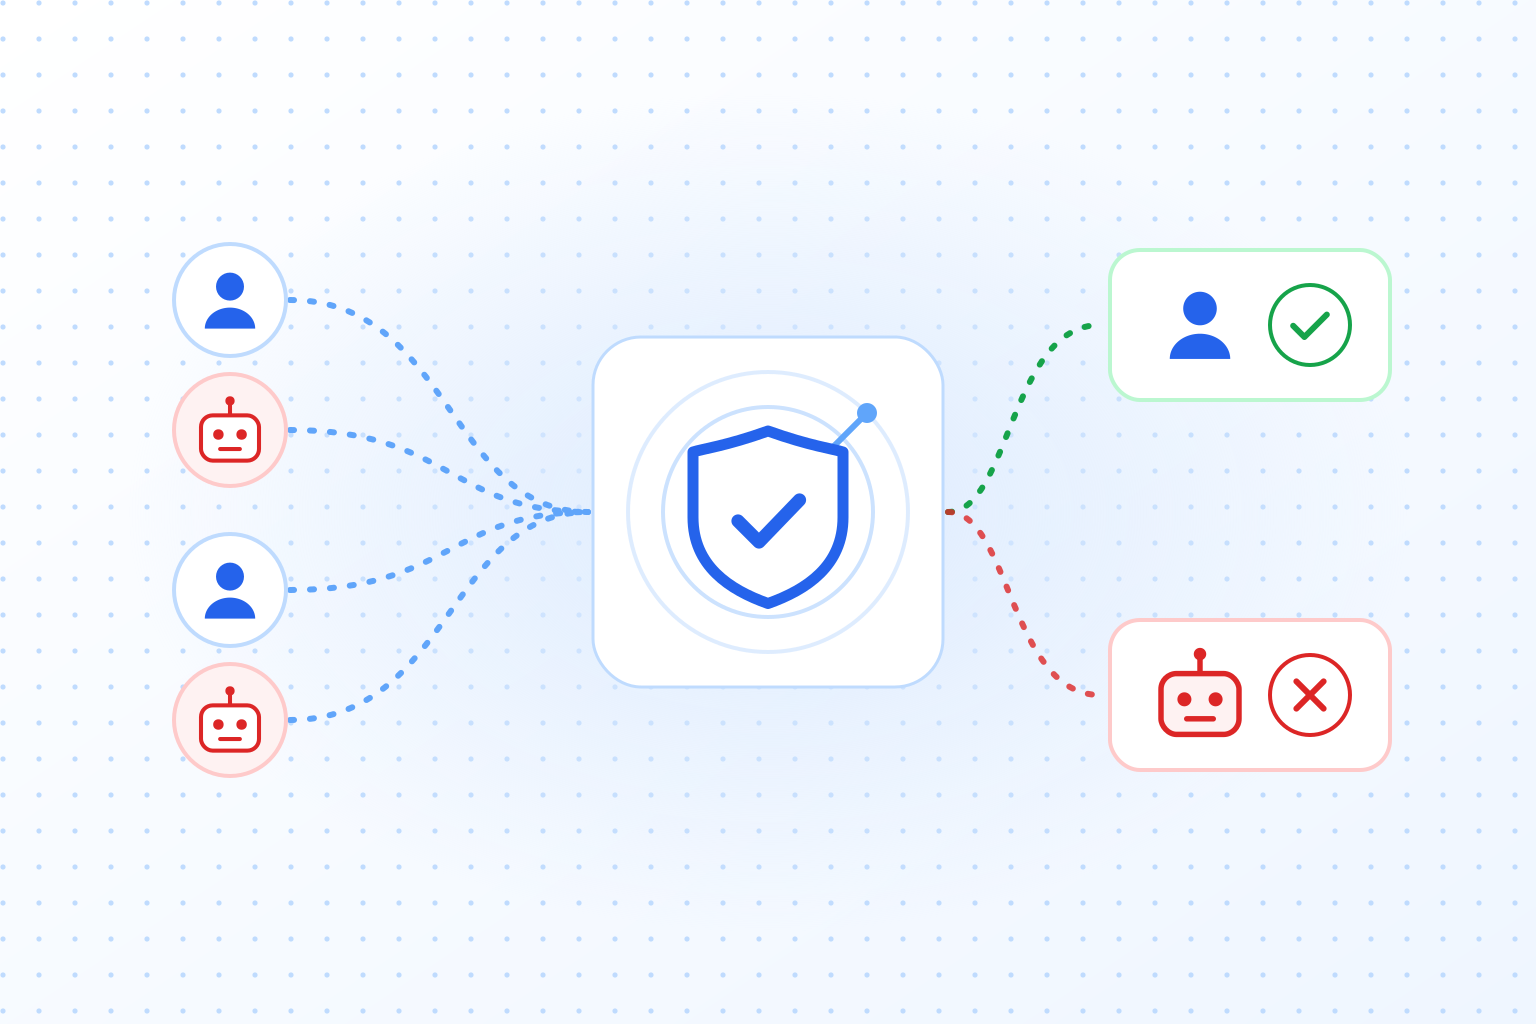
Bot detection is the process of deciding whether a request comes from a person or from a program. It looks at how the request is built, how the session behaves and what environment it runs in, then turns those signals into a decision: allow, check again or block.
Bot traffic reaches almost every part of a modern product: account creation, login, checkout, search, pricing pages, content endpoints and APIs. Some of it is useful and expected. Trouble starts when bots ignore your rules and probe for weak spots, copy content, fake engagement or use up resources. That is why it pays to treat bot traffic as an ongoing operational risk rather than a one-off cleanup.
Good bot detection identifies that traffic with confidence and stops it without hurting the user experience. TrustCaptcha, an invisible CAPTCHA that asks visitors to do nothing, is built for teams that want this protection without puzzles, interruptions or lost conversions.
What is bot traffic?
Bot traffic is any non-human traffic to a website, app or API. People often use the term to mean “bad activity”, but the picture is more mixed. Automated programs help your business when they identify themselves, behave predictably and stay within sensible limits. The same automation does harm when it hides, runs at high volume or is built to manipulate results.
Bot traffic becomes a security and reliability problem when it targets actions that carry value: authentication, transactions, stock reservations, content access, or workflows that cost you money each time they run (emails, text messages, compute, paid third-party APIs). Attackers go for whatever scales cheaply and pays off in a way they can measure. The payoff can be theft, extracted data or plain disruption.
Good bots, gray bots, and bad bots
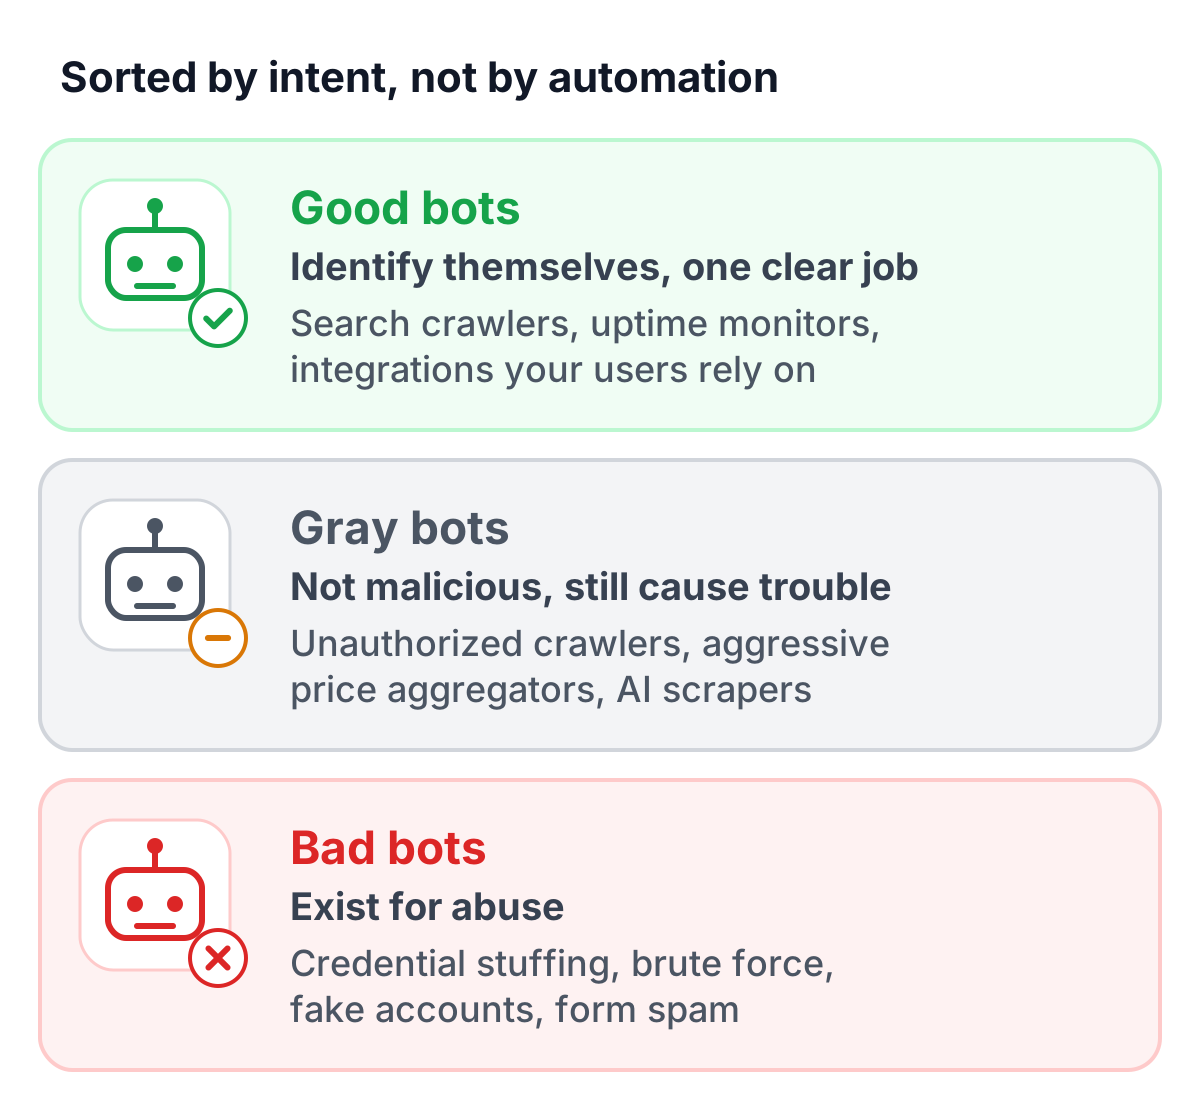
Not every bot should be blocked. A useful way to sort them is by intent and by whether they follow your rules, not by whether they are automated.
Good bots usually identify themselves and do one clear job. Search engine crawlers, uptime monitors and integrations your users rely on belong here. They are welcome as long as you can verify who they are and what they do.
Gray bots are not necessarily malicious, but they still cause trouble. Think of unauthorized crawlers, aggressive price aggregators, or AI scrapers that ignore crawl rules and drive up your costs. They pollute analytics and skew performance numbers. They can also put enough load on your servers to trigger rate limits that then hit legitimate users.
Bad bots exist for abuse. Typical patterns are credential stuffing (testing stolen usernames and passwords), brute-force login attempts, fake account creation, form spam, ad click fraud, large-scale content scraping, cart and inventory hoarding, and denial-of-service traffic. Attackers also use them to probe for weaknesses and to map your defenses.
So the goal is not to stop all automation. The goal is to let trust decide who gets into sensitive workflows: who is interacting, how they behave, and whether they can reasonably be treated as a legitimate user.
Why bot traffic is a business risk
Bot traffic is often written off as a technical nuisance. Its business impact is concrete, and it adds up. Once bots reach your product, they cause damage in at least four areas.
First, bots distort decisions. With inflated traffic, your analytics no longer reflect what users want. Product changes look like wins or losses for the wrong reasons, A/B tests lose their statistical meaning and funnel analysis stops being reliable. Teams end up shipping “optimizations” that respond to noise.
Second, bots cost money directly. Automated requests use bandwidth, server and database capacity, and third-party service quotas. Even harmless scraping can trigger expensive rendering and cache misses. For a startup that cost can hurt badly; for a large platform it still changes unit economics and capacity planning.
Third, bots erode trust. Spam accounts lower the quality of a community, fake signups pollute CRM data and automated fraud attempts add work for support. When real users run into lockouts, security warnings or slow pages, they lose confidence in the product.
Fourth, bots enable fraud. Credential stuffing turns password reuse into account takeover. Inventory hoarding leaves real shoppers with sold-out products. Automated checkout attempts and card testing turn your platform into a tool for attackers and drag your business into disputes, chargebacks and reputational damage.
That is why bot defense is not a single feature. It is part of running a service that people can trust, at any size.
How bot traffic is identified
Bot detection decides whether an interaction is more likely human or automated. Good setups combine several layers: observation at the network edge, behavior analysis in the browser or app, and enforcement at sensitive endpoints. No single signal is enough, because attackers adapt. What you want is a classification that still holds when someone is actively trying to fool it.
Engineers can often spot simple automation directly in the logs: requests that repeat a strict pattern, timing no human could produce, suspicious user agents, or bursts from a small set of IP addresses. Modern automation, however, rotates IP addresses, fakes headers and uses headless browsers to look legitimate. Detecting bots therefore also needs higher-level signals that are hard to fake consistently.
Web analytics can warn you early, but they are not a security tool. They show anomalies that should lead to an investigation and to changes in your defenses.
Analytics anomalies that often indicate bot activity
A sudden spike in pageviews that matches no campaign, launch or press mention is a common warning sign. So are odd bounce patterns, either extremely high (one page, then gone) or suspiciously low (perfect multi-page sequences), which can point to scripted browsing.
Session length can give bots away in both directions. Some bots are too fast and click through at a speed no person reaches. Others slow down on purpose to blend in, which produces sessions that are long and strangely uniform. Look at the distribution, not only at the average: human behavior is messy, while scripted behavior clusters.
Junk conversions are another sign. Form submissions with made-up names, odd email patterns, impossible phone numbers or the same template text again and again usually come from automation. In account creation, a high volume of signups from one region, network (ASN) or device profile is a strong warning sign, especially if you do not serve that region.
None of these signals proves bot activity on its own. They tell you where to add logging, where to enforce and where stronger controls are worth the effort.
Why filtering analytics is not the same as stopping bots
Many teams start by filtering known bots out of their analytics, and that is sensible housekeeping. It removes reporting noise from recognized crawlers. It does not protect your systems, though. The traffic still reaches your servers, still triggers workflows and still causes abuse. If you want to stop fraud, keep performance stable and protect users, you need enforcement, not only cleaner reports.
Put simply, filtering analytics improves measurement, and bot mitigation improves security and reliability. You want both, but they solve different problems.
The core techniques behind modern bot detection
Bot detection techniques fall into a handful of categories. Good implementations do not pick one of them; they combine them into a single decision.
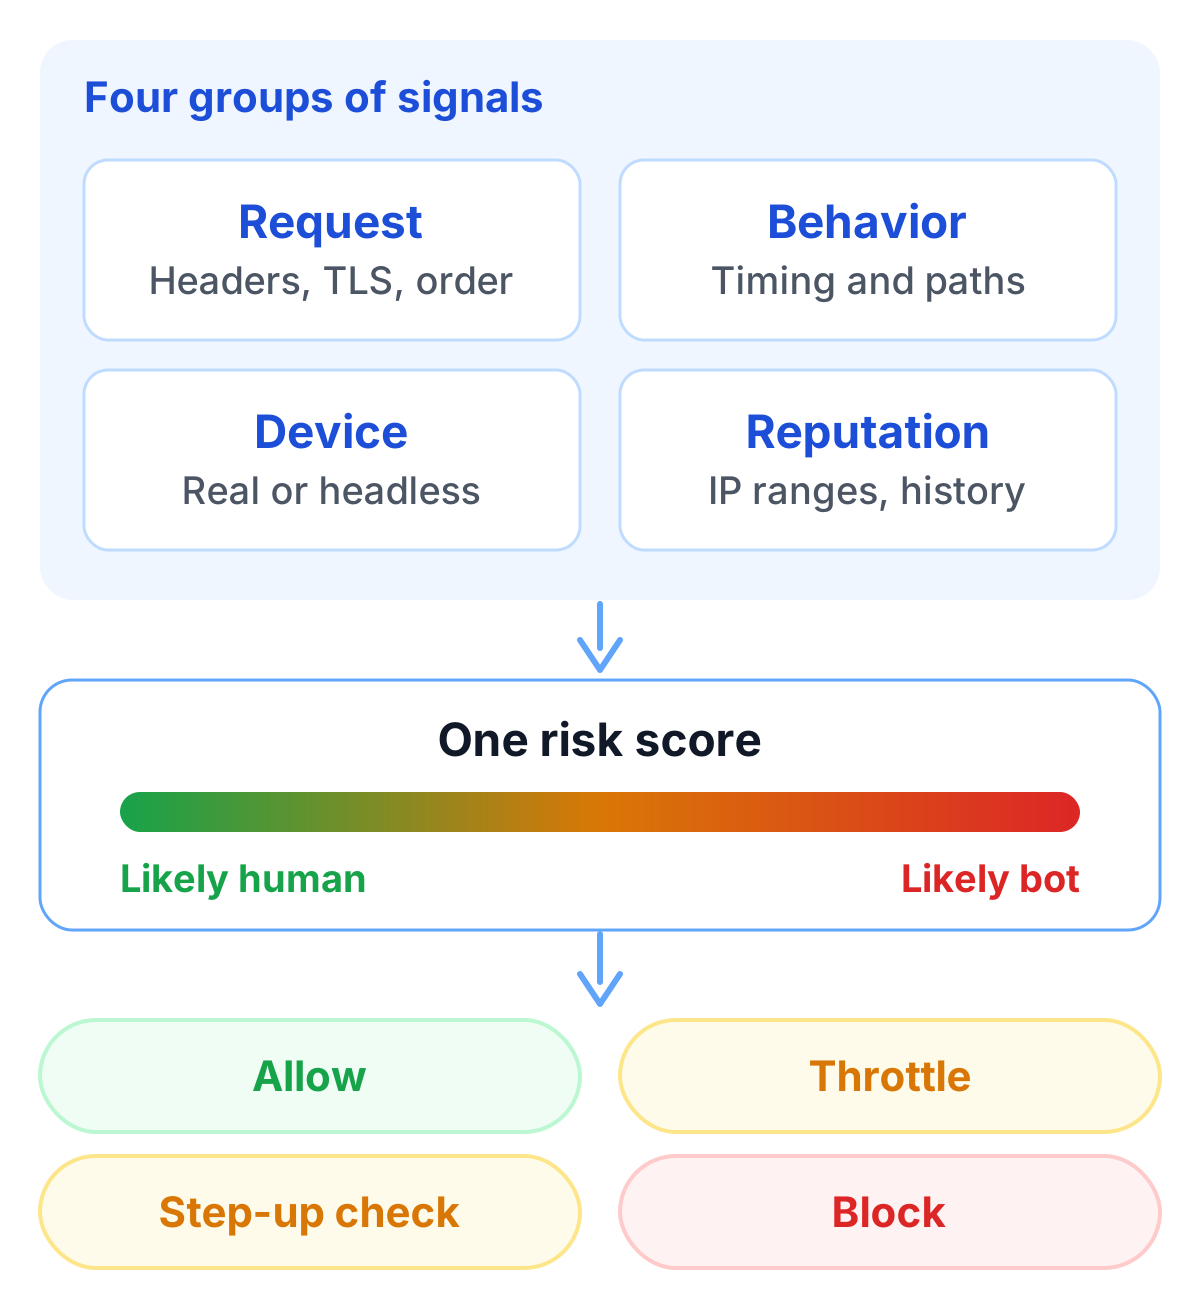
Request and protocol analysis looks at how requests are built. Bots often make small mistakes in header composition, TLS fingerprints, ordering, or consistency across requests. Even sophisticated tools leave patterns that show up at scale.
Behavioral analysis looks at how an interaction unfolds. People scroll unevenly, hesitate, fix typos and wander around. Bots tend to head straight for the goal: they submit forms with exact timing, follow perfect sequences and repeat the same pattern across sessions. Good behavioral checks rely on many small interaction signals rather than on one gesture, because many signals together are hard to imitate convincingly.
Device and environment signals check whether the browser environment looks real. Attackers often run automation in headless browsers, emulators or toolchains built to avoid detection. A defender can spot gaps between what the browser claims to be and how it actually behaves.
Reputation and threat intelligence draws on history: known abusive IP ranges, data center networks, clusters of anomalies and patterns seen across many deployments. This helps, but use it with care, or you end up blocking legitimate users who share infrastructure with attackers.
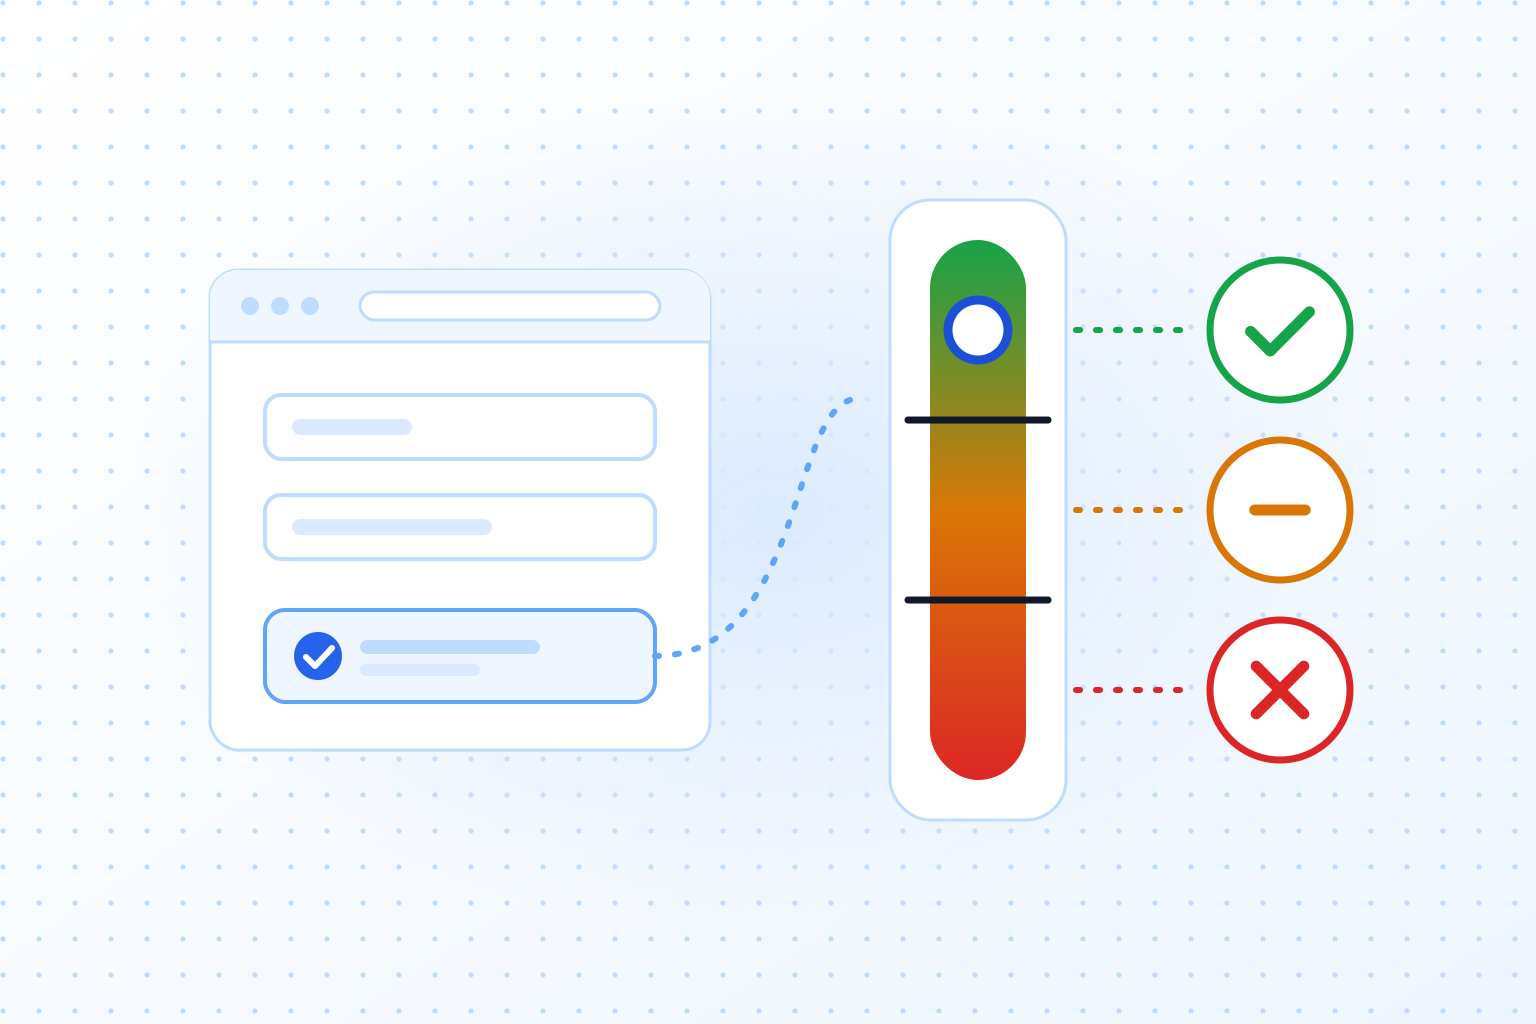
Risk scoring and adaptive enforcement turns signals into decisions. Instead of a hard “block or allow” everywhere, mature systems assign a risk score, often called a bot score, and respond differently depending on what the endpoint is worth, the state of the user and how heavy the attack is at that moment.
That is where the field is heading: fewer visible challenges and more quiet, continuous assessment.
Why traditional CAPTCHAs are no longer the right default
Traditional CAPTCHAs were built for simpler bots and smaller attacks. Today their puzzles cause three recurring problems.
They add friction for real users. Every step that interrupts a signup or checkout flow increases drop-off. When you make people solve puzzles, you pay for security with revenue.
They are hard on accessibility and trust. People with disabilities, people on weak mobile connections and people on restricted devices often find puzzles difficult or unreliable. That becomes a compliance problem as well as a brand problem.
They are getting easier to solve. Attackers send puzzles to click farms, use machine-learning solvers or hand them to paid human workers inside automated pipelines. Puzzle CAPTCHAs then end up taxing your real users while determined attackers get through anyway.
A modern approach keeps the security and gives users their time back.
How to stop bot traffic: a layered strategy
Stopping bot traffic works best in layers. Each layer raises the attacker’s cost, lowers the success rate of automation and gives you more control over the user experience.
The first layer is surface reduction. Protect only what needs protection, but protect it properly. Put defenses on the endpoints that carry value: authentication, signup, password reset, checkout, and any form that is expensive or attracts abuse.
The second layer is rate and abuse controls. Rate limits, request quotas and anomaly thresholds reduce high-volume attacks. They work well against simple bots but are rarely enough on their own, because sophisticated attackers spread their traffic.
The third layer is verification. This is where a puzzle-free check earns its place: it has to tell people from automation with little friction and be hard to bypass.
The fourth layer is response and feedback. When you block or challenge traffic, that decision should flow back into your detection, so that every attack teaches you something.
Done well, layered defense reduces both false positives and the day-to-day workload.
Where TrustCaptcha fits in bot detection
TrustCaptcha is built for teams that need strong bot protection without puzzles, page interruptions or “prove you are human” moments. It runs in the background and calculates a risk assessment from technical and behavioral signals instead of asking the user to do anything.
Users do not notice the check, and that is the point. Legitimate users finish the flow without distraction, while automated abuse hits a much higher barrier. The work moves from the user to the attacker.
The difference shows most where conversion matters. Login, signup, password reset and checkout tolerate very little friction. A check that keeps conversion intact and still stops automation stays switched on. A check that costs signups becomes an internal argument every quarter.
Proof-of-work as an additional security layer
Under heavy attack, classification alone is not always enough. When attackers can send large volumes of automated requests at low cost, bot mitigation should also make abuse economically pointless. A proven way to do that is a proof-of-work (PoW) security layer: before a sensitive action is accepted, the client has to do a small, bounded amount of computation. For a legitimate user this runs unseen and finishes quickly. For bots at scale it becomes expensive, because the attacker pays the computing cost for every single attempt.
PoW helps most against high-rate automation such as credential stuffing, scripted form submissions and traffic bursts meant to exhaust resources. Attackers can dodge blocklists and brittle fingerprints; PoW changes their cost curve instead. Every additional request has a cost that rotating IP addresses or faking headers cannot remove. That makes PoW a good complement to behavior analysis and risk scoring, especially when bots are distributed and hard to trace back to one source.
In practice, PoW brings stability. Fewer abusive requests reach expensive workflows, performance is less likely to drop during bot surges, and keeping an attack going takes more effort. Used where it counts, rather than as a gate on every page, it strengthens your bot defenses without putting obstacles in front of users.
Decision design: allow, throttle, step-up, or block
Good bot mitigation rarely relies on a single response. The response should match the risk and the value of the endpoint.
Low-risk interactions can pass while you keep watching. Medium-risk sessions can be slowed down or asked to try again. High-risk actions, such as repeated login attempts or mass form submissions, should be blocked outright. The advantage of risk-based verification is that you can be strict where it matters and relaxed where the user experience comes first.
TrustCaptcha supports this model by giving your policy something to decide on: your server receives the result together with the bot score, so you can lock down critical actions while ordinary browsing stays smooth.
Practical signals attackers struggle to fake consistently
Attackers can fake a user agent string in seconds. They can rotate IP addresses. They can imitate basic browser behavior. What is much harder is staying consistent across the whole interaction: timing, variation in navigation, the order of events and an environment that adds up.
Bot detection becomes reliable when you look at the whole session instead of single requests. People leave natural imperfections: pauses, corrections, uneven paths and changes of context. Automation produces uniformity. Even when attackers randomize behavior, the randomness tends to look artificial at scale.
A modern, invisible approach builds on these lasting differences. You will not catch every bot with one trick. What you can do is make sustained automation expensive, unreliable and visible.
A disciplined implementation approach
Bot protection works best when you measure and tune it. Start with the endpoints that are abused most and track the outcomes: submission success rates, how login failures are distributed, suspicious session clusters and what abuse costs you in support tickets, infrastructure spikes and bad data.
Deploy TrustCaptcha where you can measure the effect quickly. In many products, protecting signup and password reset pays off right away: fewer fake accounts, less spam, a cleaner CRM, lower email costs and less abuse further down the line.
Then extend coverage as you learn. The aim is not to block as much as possible. The aim is that real users get through and automated abuse fails, reliably and predictably.
Incident handling: what to do during an attack
When a bot attack picks up, your team needs a clear plan. Everyone should know which metrics signal an escalation and which actions are safe to take.
Tighten enforcement on high-value endpoints first. Lower the rate limits for clearly abusive patterns, but avoid broad blocks that hit legitimate users on shared networks. Use your verification results to split the traffic: let trusted sessions through and contain suspicious ones firmly.
After the incident, hold a short review focused on what you learned: which endpoints were targeted, which rules worked, where false positives occurred and which workflows cost more than expected. Teams that handle bots well use each attack as input for the next round of tuning.
Measuring success
A bot program succeeds when business results improve, not when it reports an impressive number of blocks. Useful indicators are a lasting drop in junk conversions, fewer spam accounts, less login abuse, steadier infrastructure load and cleaner analytics. For many organizations the clearest sign is that teams trust their metrics again and can run experiments without wondering whether automation drove the result.
TrustCaptcha helps here by stopping automated abuse while protecting the user experience those metrics describe.
Try TrustCaptcha
If you want to cut automated abuse without adding steps for your users, put TrustCaptcha where it matters most: your forms, signups, logins and checkout. It gives you bot detection that visitors never have to interact with. Dynamic proof-of-work is part of every paid plan, and bot detection with the bot score starts with the Solo plan.
Every plan starts with a 14-day free trial, and non-commercial websites can use TrustCaptcha for free. Start your free trial on your riskiest endpoints and let legitimate users carry on without interruption.